Biography
I am a Ph.D. student in Electrical and Electronic Engineering at the University of Hong Kong, supervised by Prof. Ngai Wong. I received my M.Eng. in Big Data Engineering from Tsinghua University in 2025, advised by Prof. Yujiu Yang, and my B.Eng. from Huazhong University of Science and Technology in 2021.
中文学术简历(PDF) · English CV (PDF)
Research Interests
LLM post-training; Knowledge distillation; Efficient reasoning; Low-bit quantization. My work explores model compression and efficient reasoning in large language models.
Publications
Selected published and accepted papers. Full publications and preprints (Chinese PDF).
* indicates equal contribution.
Revisiting Model Interpolation for Efficient Reasoning
Taiqiang Wu*, Runming Yang*, Tao Liu, Jiahao Wang, Ngai Wong. ACL 2026 (Main) [Paper]ProFit: Leveraging High-Value Signals in SFT via Probability-Guided Token Selection
Tao Liu*, Taiqiang Wu*, Runming Yang, Shaoning Sun, Junjie Wang, Yujiu Yang. ACL 2026 (Findings) [Paper]Can We Trust LLMs on Memristors? Diving into Reasoning Ability under Non-Ideality
Taiqiang Wu*, Yuxin Cheng*, Chenchen Ding*, Runming Yang, Xincheng Feng, Wenyong Zhou, Zhengwu Liu, Ngai Wong. COLM 2026 [Paper]Exploring Layer-wise Information Effectiveness for Post-Training Quantization in Small Language Models
He Xiao, Qingyao Yang, Dirui Xie, Wendong Xu, Zunhai Su, Runming Yang, Haobo Liu, Wenyong Zhou, Zhengwu Liu, Ngai Wong. ACL 2026 (Findings) [Paper]Rethinking Kullback-Leibler Divergence in Knowledge Distillation for Large Language Models
Taiqiang Wu, Chaofan Tao, Jiahao Wang, Runming Yang, Zhe Zhao, Ngai Wong. COLING 2025 (Oral) [Paper]LoCa: Logit Calibration for Knowledge Distillation
Runming Yang, Taiqiang Wu, Yujiu Yang. ECAI 2024 [Paper]
Industry Experience
Tencent — Research Intern
Nov. 2023 - Jun. 2025
- Synthesized multimodal data and conducted model post-training and evaluation for image-text content moderation in QQ group chats, Qzone, and short-video comments.
- Deployed models in tiers and accelerated inference; trained models were deployed in internal risk-control systems, improving throughput and reducing false-positive rates over the previous solution.
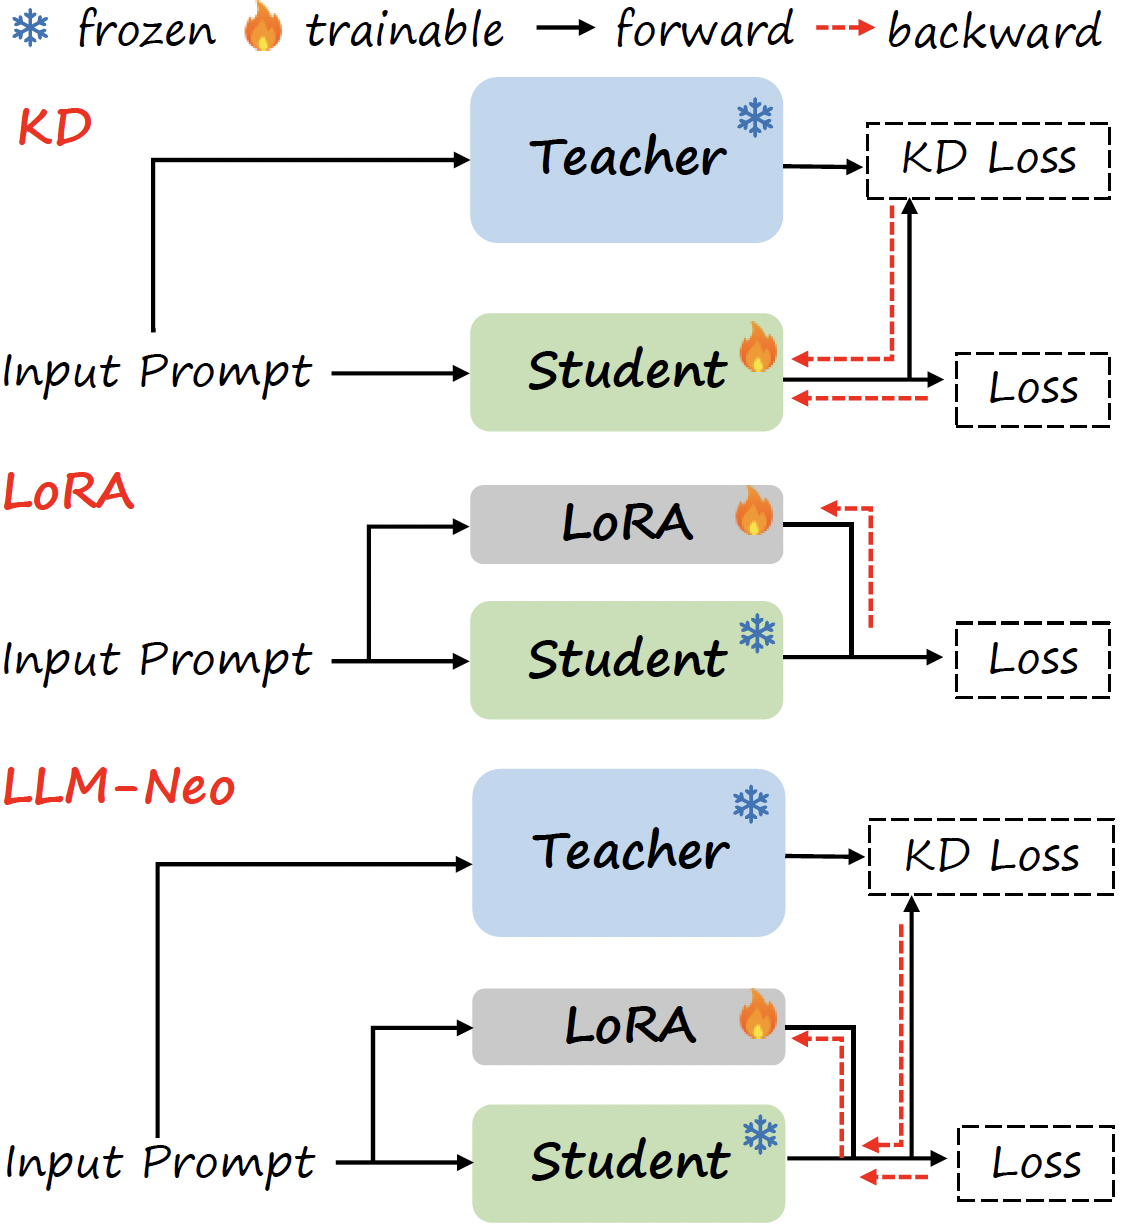
- Researched large/small model collaboration, data distillation, and lightweight modeling; contributed to two academic papers (Shadow-FT and LLM-NEO) and one company patent.
Current Research
How On-policy Distillation Affects Reasoning and Subsequent RL — 2026.09 - 2026.10
Qwen3 0.6B/1.7B/4B students; 8B primary teacher
Accuracy figures below: Qwen3-1.7B, MATH-500, 16K generation budget, avg@4.
- Designed comparisons of teacher prompts, self-distillation, and direct RL to investigate why distillation can improve downstream RL results.
- Switching the same teacher to a thinking prompt yielded 86.75% accuracy for 1.7B, versus 73.45% for the base model and 76.20% for standard OPD; self-distillation at 1.7B and 4B achieved similar results.
- Used budget curves, forced-finalization interventions, and stopping analyses to distinguish long pre-answer reasoning from continued generation after an answer, showing how correctness and timely delivery can diverge.
- Under the same downstream RL setup, distillation followed by RL reached 87.25% versus 81.70% for direct RL, with gains at lower budgets accompanied by reduced accuracy at higher budgets.